Get Started with Amazon SageMaker AI and Machine Learning
Learning objectives
After completing this unit, you’ll be able to:
- Explain what machine learning is and how it applies to business problems.
- Identify the key components of the machine learning lifecycle.
- Outline the purpose, essential concepts, and a typical workflow of Amazon SageMaker AI.
What Is Machine Learning?
Machine learning (ML) is a type of artificial intelligence that lets computer systems learn from experience. Machine learning algorithms find patterns in data and use those patterns to make predictions about new data. For example, you can predict which leads will likely convert, spot customers at risk of leaving, or automatically sort support cases by content.
This works differently from traditional programming, where you write the rules yourself, spelling out every condition and what should happen in each case. Machine learning turns that around: you supply examples of inputs and the outcomes that went with them, and the algorithm works out the rules itself. That's why ML suits problems where the rules are too numerous, too subtle, or too changeable to write down. These capabilities go beyond simple automation.
Explore the Machine Learning Lifecycle
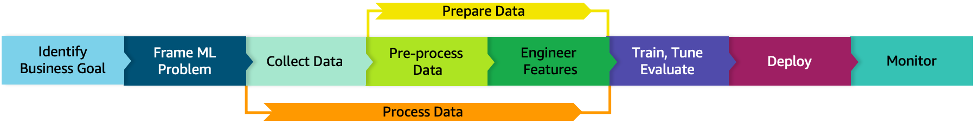
Machine learning projects follow a process with multiple phases. Let’s take a look.
-
Business goal identification is where every ML project starts. You need a clear problem to solve and expected business value. Can you measure success? What business goals will this ML solution support? Without clear answers, even the best model won’t deliver results.
- Next is ML problem framing. Here you translate your business problem into something a machine learning algorithm can solve. What are you predicting? Is this a classification problem (sorting things into groups) or regression (predicting a number)? You also define success metrics for your use case.
- With data processing, you collect relevant data, clean it to remove errors, and create features that help your model learn. Features are specific attributes from your raw data that your model uses to make predictions.
-
Model development is where you build, train, tune, and test your model. You try different algorithms, adjust settings to improve performance, and test if your model works. This often takes multiple tries as you refine your approach.
-
Deployment brings your model into production where it generates real predictions.
-
Model monitoring ensures your model keeps performing well over time. Real-world data changes, so models can drift from their original accuracy. Monitoring helps you catch issues early.
These phases aren’t strictly in order. You’ll often go back to earlier phases as you learn more. Maybe your features need work, or you need more data.
Explore Amazon SageMaker AI
Amazon SageMaker AI (formerly Amazon SageMaker) is a complete machine learning platform. It gives you everything you need to build, train, and deploy ML models at scale. The platform handles server setup, network configuration, and software updates automatically.
The platform also separates different concerns. Data prep, model training, and deployment are distinct phases with dedicated tools. This lets teams optimize each phase independently and work together better. For example, data engineers can focus on quality datasets, data scientists test modeling approaches, and DevOps teams manage production deployment (all using the same platform but different tools for their work).
Essential Concepts
Let’s review key concepts that form the foundation of SageMaker.
-
Instances and compute resources: SageMaker AI uses Amazon EC2 instances as the underlying compute infrastructure. Different instance types work best for different tasks. For example, ml.t3 instances are cost-effective for development and testing, while GPU instances in the ml.g family (such as ml.g6) work well for training deep learning models. New GPU generations arrive regularly, so check the SageMaker AI pricing page for what's available in your Region. Knowing which instance types to use helps you optimize performance and cost.
-
Endpoints: A SageMaker endpoint is a fully managed tool that hosts your trained model and provides a REST API for predictions. When you deploy a model to an endpoint, SageMaker handles infrastructure management, including load balancing and auto-scaling. Endpoints are the main way to integrate SageMaker predictions with external apps like Salesforce.
-
Training jobs: A training job uses your prepared data to train a machine learning model. When you launch a training job, you specify the algorithm, data location, and compute resources needed. SageMaker sets up the infrastructure, runs training, and stores the resulting model artifacts in Amazon S3.
-
Models and model artifacts: In SageMaker, a model consists of the algorithm and learned parameters (weights) from training. These model artifacts are stored in Amazon S3 and can be deployed to endpoints for predictions. You can also version models and deploy the same model to multiple endpoints if needed.
-
Feature engineering: Features are the input variables your machine learning model uses to make predictions. Feature engineering transforms raw data into features that better show the patterns in the data. For example, suppose you have a dataset with customer information stored in a table. The table contains columns like purchase history, account age, support ticket count, or last login date. Each column is a potential feature. During feature engineering, you choose which columns to use and can create new ones by combining or changing existing data. Better features mean better model performance.
-
Built-in algorithms and pretrained models: SageMaker includes built-in algorithms optimized for performance and scale. These cover common use cases like classification, regression, clustering, and more. SageMaker JumpStart provides pretrained models and example notebooks to speed up development. You can also bring your own algorithms and frameworks for specific needs.
Follow the Typical SageMaker Workflow
Let’s look at how you’d work with SageMaker AI to create a machine learning model. We focus on three key stages that map to the lifecycle phases covered earlier: collecting and processing data, training a model, and deploying the model.
Stage 1: Collect and Process Data
This is your starting point. You need training data that represents the problem you’re solving. If you’re building a model to predict customer churn, you need historical data about customers who stayed and customers who left. Data scientists spend significant time in this stage. The quality of your training data directly impacts your model quality.
This stage involves fetching data from various sources (like your Salesforce org, data warehouses, or public datasets), cleaning it for consistency, and transforming it to make patterns more visible. SageMaker provides several tools for this work. You can use Data Wrangler (available within SageMaker Canvas) to visually prepare data, or write code using the SageMaker Python SDK in a notebook. For advanced scenarios, SageMaker Feature Store lets you create a central repository of features to reuse across multiple models.
Stage 2: Train a Model
This is where the actual learning happens. You choose an algorithm (SageMaker provides many built-in options, or bring your own), specify your training data location, and configure the compute resources you need. When you launch a training job, SageMaker handles infrastructure setup, runs training, and stores the resulting model artifacts.
Training isn’t just running an algorithm once. You test your model’s performance using test data, adjust hyperparameters to improve results, and often train multiple versions before you’re satisfied. MLflow helps you track all these iterations so you can compare results and see what works best.
Stage 3: Deploy the Model
This is where you make your trained model available for generating predictions. SageMaker lets you deploy models to fully managed endpoints for real-time, serverless, or asynchronous processing.
After deployment, the cycle continues. You monitor your model’s performance, collect new data, and retrain periodically to maintain accuracy.
Wrap Up
You’ve now covered the basics of machine learning: what it is, how it differs from traditional programming, and why it’s valuable for solving business problems. You’ve explored the complete ML lifecycle and learned how Amazon SageMaker supports each phase with purpose-built tools and managed infrastructure. In the next unit, you dive deeper into SageMaker’s specific capabilities and explore how different SageMaker services work for common integration scenarios.